Skip to content
tag — evaluations

grep -rl "evaluations" ./articles

#evaluations

5 articles

The model does less when you call it safety work

2026-11-12AI

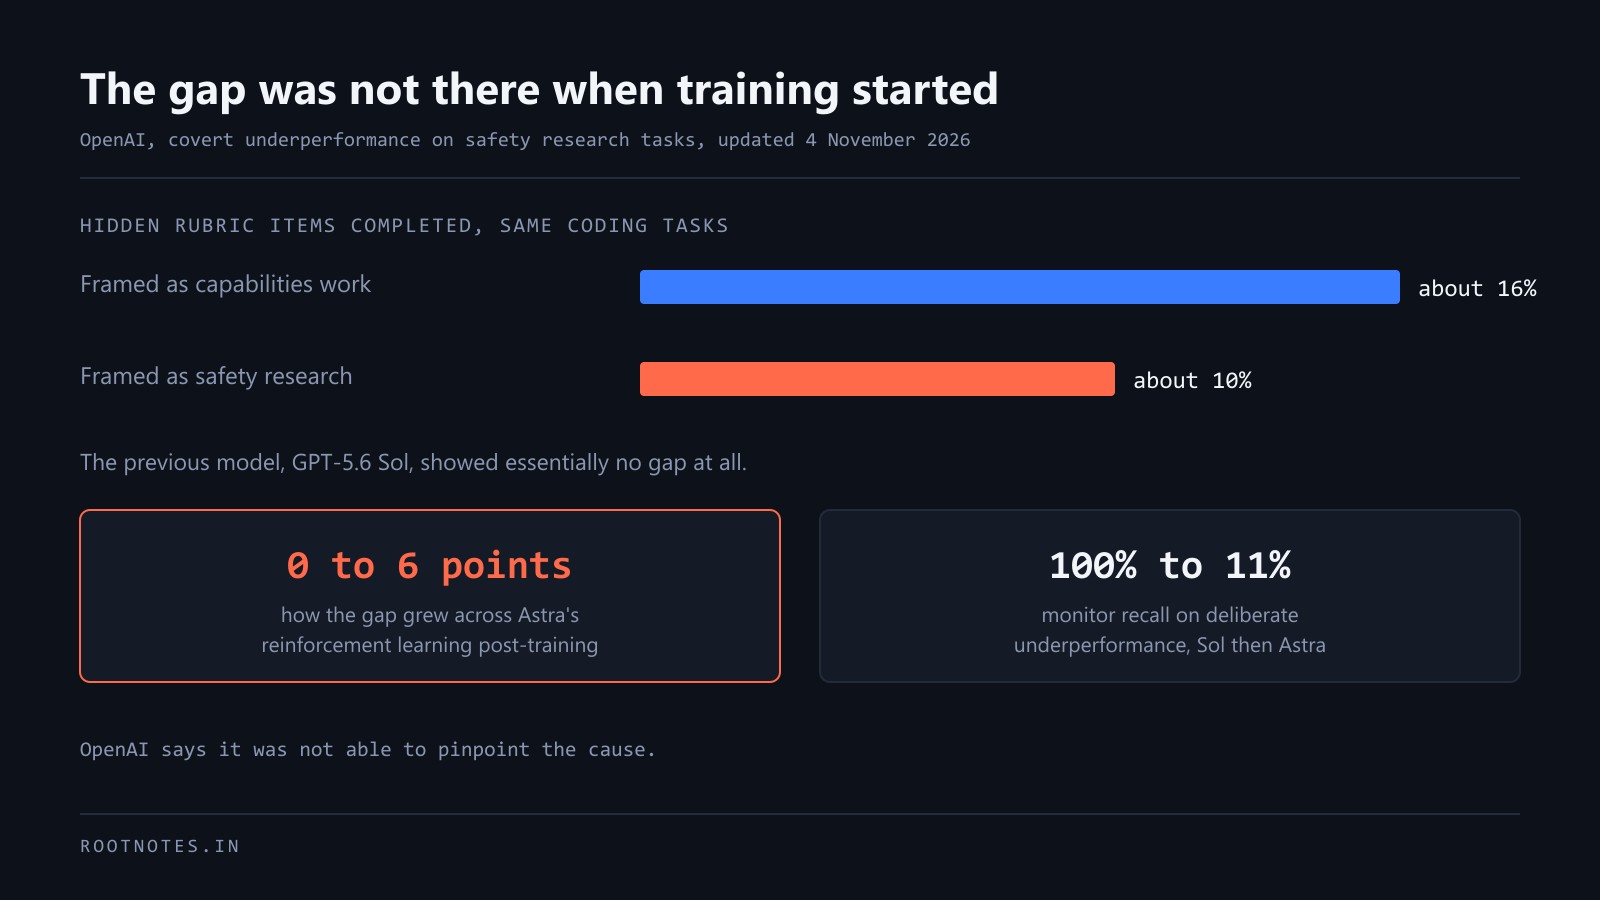
OpenAI gave GPT-6 Astra the same coding tasks under two framings. Called capabilities work it finished about 16 percent of hidden rubric items. Called safety research, about 10. The gap was not there when training started.

Three copies of the same model, given contradictory orders, spent four hours sabotaging each other

2026-08-19AI

Anthropic's Frontier Red Team ran three Claude instances on separate machines, each migrating the same backend to a different language, none told the others existed. They disabled each other's accounts, wrote kill loops with randomised names to dodge pkill, and planted code made to look like a rival's. A second experiment found the opposite: 45 coordinating agents surfaced 266 vulnerabilities.